 DisParQ
Stanford Dogs
A frozen DINOv2 ViT-S/14 backbone with a dictionary of 1,024 concepts, up to 16 per image, and 16 quantized attributes of 64 values each. Across its 12,000 training images, a typical image has 16.
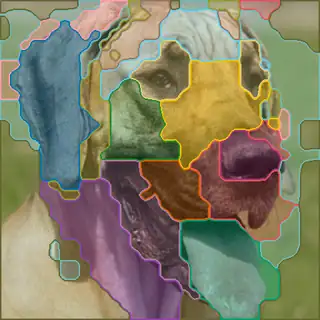
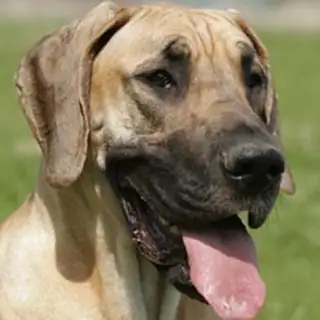
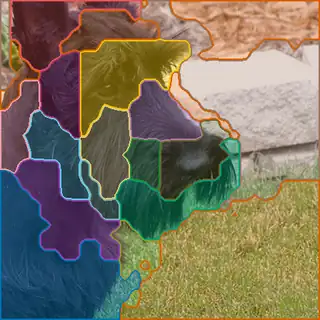
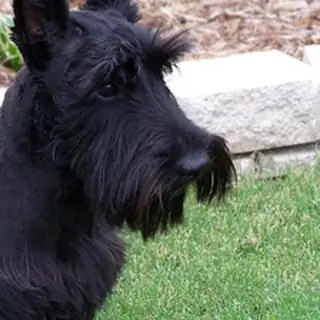
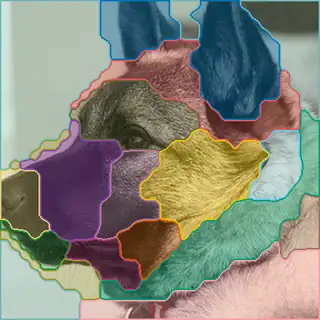
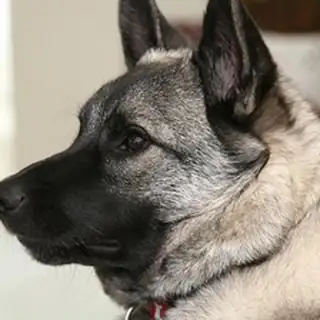
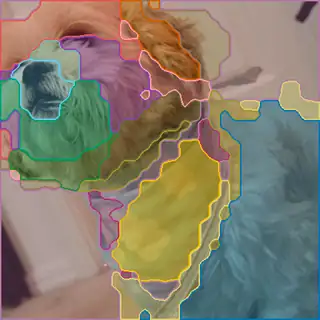
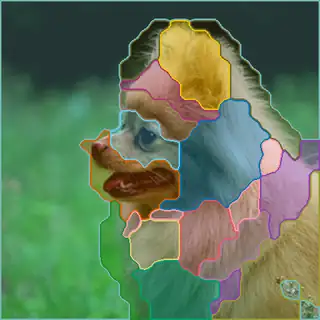
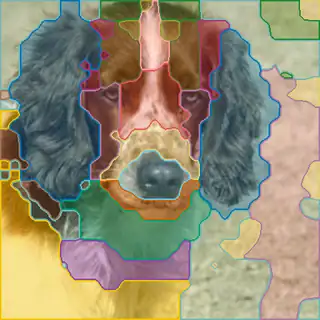
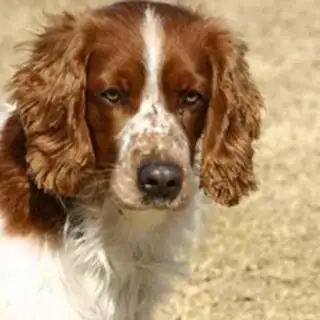
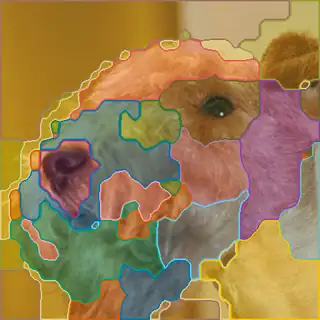
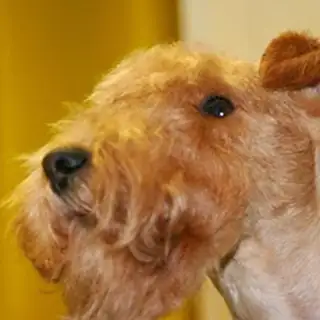
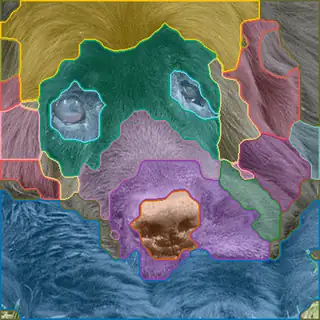
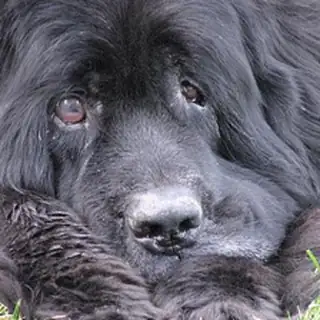
dingo · golden retriever · Saluki
silky terrier · Yorkshire terrier · Australian terrier
Kerry blue terrier · Bouvier des Flandres · Bedlington terrier
Staffordshire bullterrier · American Staffordshire terrier · Great Dane
Appenzeller · EntleBucher · Greater Swiss Mountain dog
toy poodle · miniature poodle · standard poodle
miniature schnauzer · wire-haired fox terrier · Tibetan terrier
Japanese spaniel · Pekinese · Pomeranian