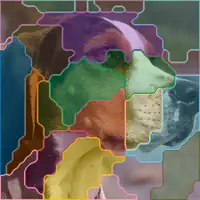
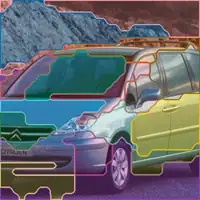
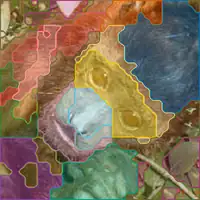
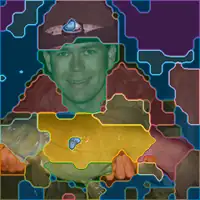
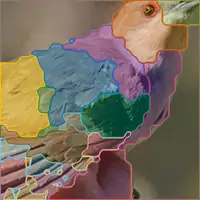
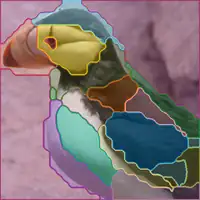
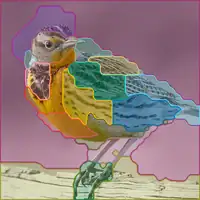
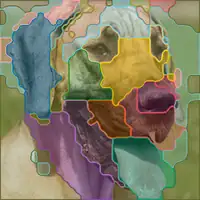
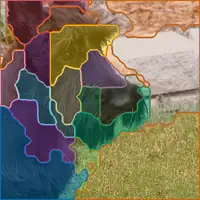
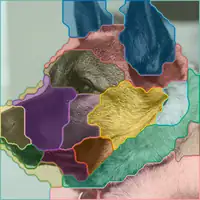
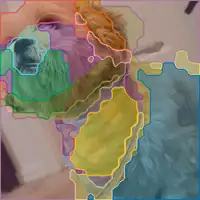
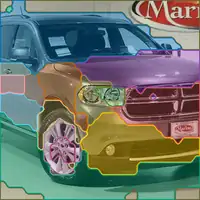
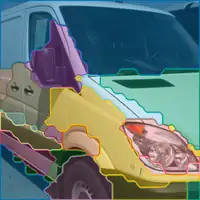
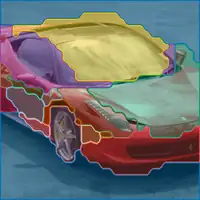
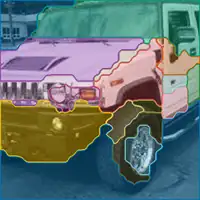
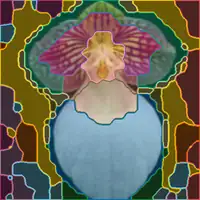
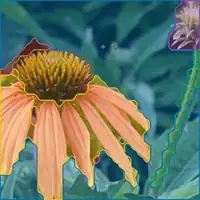
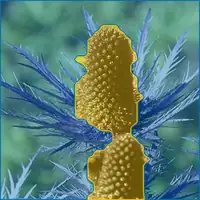
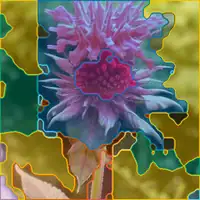
DisParQ describes an image with discrete part concepts, learned from a frozen self-supervised backbone without class labels or language. Each image patch is assigned to exactly one concept from a learnable dictionary, only a small set of concepts is active in each image, and quantized attributes capture how a concept varies from image to image.
 DisParQ
/